1. Introduction
Transformer-based large language models have substantially improved contextual understanding and natural response generation, enabling chatbots to serve as virtual teaching assistants in foreign-language learning. However, a fluent response is not necessarily pedagogically appropriate. LLMs may generate unsupported information, provide explanations that are too difficult for novice learners, or offer the same type of support to learners with different goals and weaknesses. In educational settings, such mismatches not only reduce the learning experience but may also reinforce inaccurate language knowledge.
Rule-based chatbots provide good control over content but are limited in handling diverse expressions and multi-turn conversations. In contrast, LLM-based chatbots are highly flexible but often lack long-term learning memory, learner-aware retrieval mechanisms, and adaptive prompting. The core gap therefore lies in combining the language-generation capability of LLMs with validated knowledge sources and a continuous adaptation loop driven by the learner profile.
This paper presents the model PCB = f(LLM, RAG, LP, AP), where LP denotes the learner profile and AP denotes the adaptive prompt. The two main technical contributions are: (i) a retrieval scoring function that combines semantic relevance, profile matching, and CEFR-level alignment; and (ii) a five-block prompting framework that automatically modulates linguistic complexity and response strategy. The system is evaluated in terms of retrieval quality, generation quality, faithfulness, personalization, and learner experience.
2. Approach and proposed architecture
RAG adds an external knowledge layer to an LLM: the query is encoded into a vector, relevant passages are retrieved, and those passages are then supplied as generation context. This approach enables knowledge updates without retraining the base model and provides evidence for post-generation verification [6]. However, conventional RAG remains content-centric; the same query typically returns the same context for every learner. In foreign-language learning, relevance must answer two questions simultaneously: is the content on topic, and is it at an appropriate level for the learner?
2.1. Learner profile and adaptive loop
The learner profile is represented as P = ⟨L, V, G, M, H, S⟩, corresponding to CEFR level, vocabulary state, grammar state, error log, interaction history, and learning goals. After each turn, the knowledge-tracing module updates mastery levels and weaknesses; this information then feeds back into both retrieval and generation. Bayesian Knowledge Tracing is used to estimate mastery probability over time [9, p. 253-278], combined with decay based on the interval between review sessions. Personalization therefore extends beyond topic selection and becomes a closed-loop adaptation process.
2.2. CEFR-aware hybrid retrieval
The system combines BM25 with dense retrieval based on sentence embeddings. The two ranked lists are merged using Reciprocal Rank Fusion, then filtered by metadata and diversified using Maximal Marginal Relevance. The final ranking score of knowledge passage cᵢ for query q and learner profile p is defined as follows:
Score(q, cᵢ, p) = αSim(q, cᵢ) + βProfileMatch(p, cᵢ) + γDiffAlign(p, cᵢ), where α + β + γ = 1. The Sim component measures semantic similarity; ProfileMatch prioritizes content related to the learner’s goals and weaknesses; and DiffAlign measures alignment between document difficulty and CEFR level. This formulation incorporates pedagogical signals directly into retrieval rather than adding learner-profile information only at the prompting stage.
2.3. Conversational pipeline and adaptive prompting
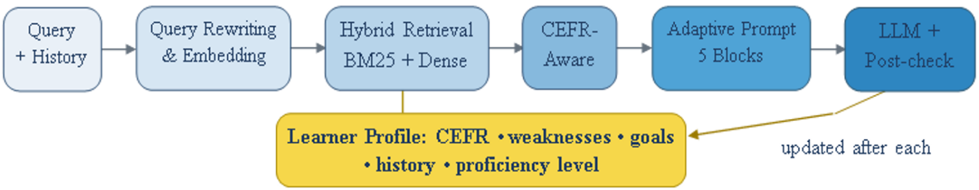
Fig. Personalized RAG pipeline and learner-profile update loop
The pipeline consists of six steps: query rewriting using conversation history; encoding; hybrid retrieval; personalized ranking; context augmentation; and prompt construction followed by response generation with post-checking. The prompt is organized into five blocks: system role, learner profile, retrieved knowledge, compressed conversation history, and task instructions. For A1–A2 learners, the system prioritizes short sentences, high-frequency vocabulary, direct correction, and worked examples; at B1, it increases syntactic diversity, reduces scaffolding, and encourages self-correction. A response is accepted only when it remains well grounded in the retrieved context; when confidence is low, the response is shortened or the learner is asked for clarification.
3. Experimental design
3.1. Data, models, and configuration
The knowledge base was built from four groups of English-learning resources: Cambridge Grammar (approximately 1,100 documents), Oxford Dictionary (1,400), CEFR resources (350), and British Council materials (600), for a total of approximately 3,450 documents. The text was normalized, segmented with overlap, annotated with topic and CEFR metadata, and indexed in ChromaDB/FAISS. The evaluation set consisted of 250 queries: vocabulary (60), grammar (60), reading comprehension (40), speaking simulation (40), and everyday conversation (50). From these queries, 500 dialogue pairs were used for generation evaluation and configuration analysis.
Three generative models were examined: GPT-4o, Llama 3 Instruct 8B, and Gemma 3 12B; the two open models were quantized to 4-bit precision for local deployment. Generation parameters were kept consistent: temperature 0.2, top-p 0.9, top-k 40, and a maximum of 1,024 tokens; the number of retrieved passages added to the context was k = 5. This configuration prioritizes stability and reduces randomness in knowledge-intensive responses.
Table 1
Experimental scenarios and investigated variables
Scenario | Components | Evaluation objective |
S0 | LLM | Baseline; intrinsic capability and hallucination tendency |
S1 | LLM + RAG | Contribution of retrieval to accuracy and faithfulness |
S2 | LLM + RAG + LP + AP | Contribution of learner profile and adaptive prompting |
CEFR | S2 with A1/A2/B1 profiles | Ability to adjust difficulty and support level |
3.2. Multi-level evaluation framework
Evaluation was conducted at five levels. First, retrieval effectiveness was measured using Precision@5, Recall@5, MRR, and NDCG@5; three-level relevance labels were independently assigned by two language experts. Second, generated responses were compared with reference answers using BLEU, ROUGE-L, BERTScore, and semantic similarity. Third, faithfulness was measured using hallucination rate, Faithfulness, Groundedness, and Context Precision. GPT-4o served as the judge, while 20% of the samples were reviewed by experts to calibrate the evaluation procedure.
Fourth, personalization capability was quantified using Learner Adaptation Score, Personalization Accuracy, Personalization Gain, and CEFR Alignment Score. The CEFR Alignment metric maps the distance between the predicted response level and the target level to the interval [0,1]; values closer to 1 indicate better difficulty alignment. Fifth, user experience was surveyed with 45 learners, evenly divided into three groups–A1, A2, and B1 (15 learners per group)–using a 5-point Likert scale. The seven criteria were usefulness, ease of use, perceived accuracy, adaptability, engagement, satisfaction, and intention to continue using the system.
3.3. Analysis method
In addition to direct comparison of S0–S2, the study performed ablation analysis at four levels: baseline GPT; GPT + RAG; GPT + RAG + Profile; and the full configuration with Adaptive Prompting. Because the quality scores were not normally distributed, the Wilcoxon Signed-Rank test was applied to paired data at a significance level of 0.05; a paired t-test was used as a secondary comparison. This design helps isolate the contributions of retrieval, learner profiling, and adaptive prompt generation.
4. Results and discussion
4.1. Retrieval and generation quality
Table 2
Performance of the three retrieval strategies
Method | Precision@5 | Recall@5 | MRR | NDCG@5 | Recall@10 |
BM25 | 0.62 | 0.58 | 0.67 | 0.64 | 0.69 |
Dense | 0.74 | 0.71 | 0.79 | 0.77 | 0.80 |
Hybrid | 0.83 | 0.80 | 0.86 | 0.85 | 0.88 |
Hybrid retrieval outperformed BM25 and Dense retrieval on all metrics. An NDCG@5 of 0.85 indicates that relevant documents were not only retrieved more frequently but also ranked higher. Recall increased from 0.80 at k = 5 to 0.88 at k = 10, suggesting that some relevant documents lie near the context boundary; however, using more passages must be balanced against noise and the token budget. These results support combining keyword and semantic signals rather than relying on a single retrieval method.
For generation quality, GPT-4o achieved BLEU 0.42, ROUGE-L 0.58, BERTScore 0.91, and semantic similarity 0.89. Llama 3 8B achieved 0.36, 0.51, 0.87, and 0.84, respectively, while Gemma 3 achieved 0.34, 0.49, 0.86, and 0.83. The gap in BERTScore was smaller than that in BLEU, indicating that the local models preserved meaning reasonably well even when their wording differed from the reference answer. This provides a basis for considering open models when privacy and cost are more important than absolute performance optimization.
4.2. Impact of RAG and personalization
Table 3
Summary results by system configuration
Configuration | Composite score | Hallucination | Faithfulness | Satisfaction |
LLM | 0.68 | 23.4% | 0.71 | 3.6/5 |
LLM + RAG | 0.81 | 7.8% | 0.92 | 4.0/5 |
RAG + LP + AP | 0.88 | 6.5% | – | 4.4/5 |
RAG reduced the hallucination rate by 15.6 percentage points, corresponding to a relative reduction of approximately 67%, while increasing Faithfulness from 0.71 to 0.92. This confirms the role of the validated knowledge base as a grounding anchor. When the learner profile and adaptive prompt were added, the composite score increased by a further 0.07 and satisfaction rose from 4.0 to 4.4, while the hallucination rate decreased only slightly. Thus, retrieval contributes primarily to content correctness and reliability, whereas personalization mainly adds pedagogical value and improves the learner experience.
Ablation results show that Accuracy increased from 0.65 for the baseline GPT configuration to 0.82 after adding RAG, to 0.87 after adding the learner profile, and to 0.92 after adding Adaptive Prompting. Each personalization step yielded an increase of 0.05, indicating that modulating prompt structure according to CEFR provides independent value rather than merely repeating profile information. Comparing LLM with LLM + RAG yielded a mean difference of +0.13 (p < 0.001); comparing LLM + RAG with the full system yielded +0.07 (p = 0.003).
4.3. Adaptation across CEFR levels
For A1, A2, and B1, the Learner Adaptation Score was 0.88, 0.86, and 0.83, respectively, while CEFR Alignment reached 0.91, 0.89, and 0.86. Personalization Gain remained positive across all three levels (+0.15, +0.13, and +0.11). Corresponding satisfaction scores were 4.4, 4.3, and 4.2/5. The slight decline as proficiency increased reflects the greater challenge of adjusting nuance, collocation, and complex structures; nevertheless, the stability across groups indicates that the adaptation mechanism is not optimized only for beginners.
Table 4
Learner experience survey results (n = 45)
Criterion | Mean score | Standard deviation |
Usefulness | 4.5 | 0.50 |
Ease of use | 4.3 | 0.60 |
Perceived accuracy | 4.2 | 0.63 |
Adaptability | 4.4 | 0.58 |
Engagement | 4.4 | 0.56 |
Satisfaction | 4.4 | 0.55 |
Intention to continue using | 4.5 | 0.50 |
The mean scores for all seven criteria were at least 4.2. Usefulness and intention to continue using the system both reached 4.5/5, while perceived accuracy was the lowest but still achieved 4.2/5. This pattern is consistent with the technical results: learners highly valued the system’s support and adaptability while maintaining reasonable caution toward model-generated content. Therefore, in practical deployment, source citation and mechanisms for reporting incorrect responses should be treated as part of the user-experience design rather than merely as back-end technical functions.
4.4. Deployment implications and limitations
The results indicate that the architecture is suitable as a virtual teaching assistant for out-of-class practice rather than as a replacement for teachers. Locally deployed open models offer greater control over data and cost, whereas GPT-4o is preferable when generation quality is prioritized. In both deployment options, post-generation verification and transparent display of retrieved evidence should be retained as core safety layers. The system should also allow teachers to review learners’ error histories and progress rather than providing only a conversational interface for learners.
The study has four limitations. First, response quality depends on the coverage and freshness of the knowledge base. Second, the retrieval–ranking–generation chain increases latency, especially on local hardware. Third, the personalization metrics mainly measure performance at the time of interaction and do not yet demonstrate long-term learning gains. Fourth, the survey sample of 45 learners and 500 dialogue pairs is suitable for an experimental study but is not sufficient for strong generalization across diverse learner populations. The use of an LLM-as-a-judge may also introduce model bias despite expert review.
5. Conclusion and future work
This paper presented an English-learning chatbot architecture that integrates LLMs, RAG, and personalization throughout the pipeline from retrieval to response generation. CEFR-aware retrieval scoring helps select knowledge that is both topically relevant and appropriate to the learner’s proficiency level; the learner profile and five-block prompt transform interaction history into concrete support strategies. On the experimental dataset, hybrid retrieval achieved NDCG@5 = 0.85; RAG reduced hallucination from 23.4% to 7.8%; and the full configuration achieved a composite score of 0.88, Accuracy of 0.92, and satisfaction of 4.4/5. Statistical tests indicate that the improvements from both RAG and personalization are significant.
Future work will include expanding the knowledge base and enabling automatic updates; integrating audio data for listening, speaking, and pronunciation practice; reducing latency through asynchronous retrieval, context compression, and quantization; and conducting longitudinal studies with larger samples to measure actual learning gains. Another important direction is to identify root causes of errors, classify errors by skill, and adapt review schedules to mastery states, ultimately moving toward an intelligent tutoring system capable of providing long-term support.